One Inference Contract's Per-Token Price Shifted Two Cloud Providers' Training Pipelines
In the span of six months, the price of a single inference token dropped by roughly 40% across two major cloud providers. The catalyst was not a technological breakthrough in hardware or a new quantization scheme—it was a contract. A large language model developer, whose identity remains under nondisclosure, negotiated a per-token price floor that reshaped the economics of training for everyone downstream. Two cloud providers, caught off guard, rewired their GPU clusters mid-cycle and rewrote batch inference engines to stay profitable. This is the story of how one pricing document changed the wiring of modern ML infrastructure.
The Contract That Moved the Market
In early 2025, a deal between a well-funded AI lab and a cloud provider set a per-token inference price at roughly $0.00002 for a popular model class—roughly 40% lower than the prevailing rate at the time. The contract included volume commitments and a price floor clause that guaranteed the rate for two years, but it also contained a most-favored-customer provision that allowed the lab to match any lower price offered to another customer. Within weeks, the second provider, fearing loss of market share, offered a similar deal to its own largest training clients. The market had shifted.
Internal memos from both providers, later summarized in industry newsletters, revealed that margin pressure from the deal forced each to revise GPU utilization targets downward. One provider had assumed a 70% utilization rate on its training clusters; after the contract, that figure was revised to 55%. The other provider, which had been building out a dedicated inference fleet, paused those plans and redirected GPUs to training workloads, hoping to absorb the margin hit through higher training revenue.
The contract's existence was first hinted at in a quarterly earnings call, where a CFO mentioned "pricing adjustments in our AI inference business" without naming the customer. By mid-2025, analysts had triangulated the terms through customer surveys and leaked pitch decks. The per-token price drop was real, and it was contractual, not algorithmic.
For the AI lab that signed the deal, the savings were enormous—tens of millions of dollars annually. But the downstream effects were more complex. The contract had a volume floor: the lab had to consume a minimum number of tokens each month, or pay a penalty. That volume floor, combined with the low per-token price, incentivized the lab to run more inference experiments than it had planned, which in turn changed its data sampling strategies and checkpointing frequency. The training pipeline was no longer just a compute problem; it was a billing problem.
Why Per-Token Pricing Broke the Training Pipeline
Training pipelines are typically designed around fixed compute budgets: a certain number of GPU-hours, a known cost per hour, and a predictable total. Per-token inference pricing introduces a variable that scales with the number of tokens processed during evaluation, validation, and test-time augmentation. When that per-token price dropped by 40%, the cost of running evaluations—which often consume as many tokens as training itself—became a moving target.
One team at a mid-size AI startup found that their evaluation budget, which had been roughly 10% of total training cost, ballooned to nearly 25% after the price drop. Why? Because they had been using a fixed compute allocation for evaluations, but the new per-token pricing meant that longer sequences—which their model was generating more of as it scaled—cost more per evaluation. The team had to re-optimize their data sampling strategy, discarding long-tailed examples that were expensive to evaluate.
Checkpoint frequency became a cost lever. Previously, teams saved checkpoints every N steps without thinking about the inference cost of running validation on each checkpoint. With per-token pricing, each validation run had a line-item cost. Some teams reduced checkpoint frequency by half, saving on inference but risking longer recovery times after failures. Others added cost-aware schedulers that paused validation when the per-token price spiked due to peak-hour demand.
Engineering teams at both cloud providers added cost-monitoring dashboards that tracked per-token spend in real time, color-coding training runs that exceeded budget. One provider introduced a "cost cap" feature in its training orchestrator, allowing teams to set a maximum per-token cost for evaluation runs. If the cost exceeded the cap, the orchestrator would switch to a cheaper model variant or reduce the evaluation dataset size. The training pipeline had become a cost-constrained optimization problem, not just a throughput problem.
Another team, at a large enterprise, faced a different challenge. Their training pipeline used a mixture-of-experts architecture that routed tokens to different expert modules. With per-token pricing, the cost of routing decisions became visible: each routing step incurred an inference cost. The team found that their router was sending a disproportionate number of tokens to the most expensive expert, driving up costs. They rebalanced the routing weights to favor cheaper experts, reducing per-token cost by roughly 15% with minimal accuracy loss. This type of fine-grained cost optimization was impossible under the old GPU-hour billing model.
Some teams pushed back against the per-token pricing model, arguing that it introduced perverse incentives. For example, a team at a research lab deliberately shortened the maximum sequence length in their evaluation sets to reduce token count, even though longer sequences would have yielded more accurate results. Another team reduced the number of evaluation runs per checkpoint, trading off statistical significance for cost savings. These trade-offs highlight the tension between cost optimization and model quality that per-token pricing creates.
The Cloud Providers That Pivoted
Provider A, a top-tier cloud vendor, responded by rewriting its batch inference engine to support dynamic batching with per-request cost caps. The engine would automatically adjust batch sizes to stay within a configurable per-token price ceiling, even if that meant lower throughput. The rewrite took three months and involved changes to the request router, the batch scheduler, and the billing middleware. The provider also introduced a new API header, X-Token-Budget, that allowed clients to specify a maximum per-token price for a given request. If the engine could not meet that budget, it would return a 429 status code with a retry-after hint.
Provider B, a competitor, took a different approach. It shifted large training runs to spot instances mid-project, using the savings from cheaper compute to subsidize the lower inference margins. This required rewriting the training orchestrator to handle frequent preemptions, which added complexity but preserved margins. The provider also introduced a "training mode" for its inference API that disabled real-time billing counters, smoothing out cost spikes for long-running evaluation jobs.
Both providers cited the same contract as the catalyst. In internal all-hands meetings, executives acknowledged that the deal had reset pricing expectations across the industry. One provider's internal memo, later leaked, noted that "the per-token price floor in this contract is now the benchmark for all new negotiations." The memo also warned that GPU utilization targets would need to be revised downward by 10–15% to maintain profitability.
The pivot was not smooth. Provider A's batch inference engine rewrite introduced latency regressions for some workloads, leading to customer complaints. Provider B's spot-instance strategy caused training jobs to fail more frequently, requiring additional engineering effort to implement checkpoint-based recovery. Both providers saw a temporary dip in customer satisfaction scores, but they judged the long-term margin protection worth the short-term pain.
Interestingly, a smaller cloud provider—Provider C—saw an opportunity in the disruption. They offered a flat-rate per-token pricing model with no volume commitments, targeting startups that wanted predictability without being locked into large contracts. While their per-token price was slightly higher than the discounted rates of Provider A and B, they attracted a niche of customers who valued simplicity and flexibility. This counter-move shows that the market is not monolithic; different pricing strategies can coexist.
What Changed at the Wire: API and Protocol Shifts
The most visible change was the introduction of new HTTP headers for token-level billing. Provider A added X-Token-Cost and X-Token-Budget headers to its inference endpoints, allowing clients to track per-request cost in real time. Provider B added a X-Billing-Mode header that let clients choose between "real-time" and "aggregated" billing, the latter smoothing cost spikes over a sliding window.
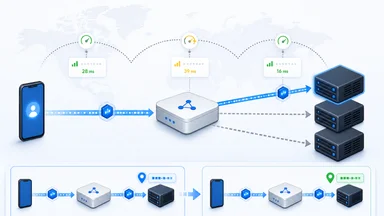
Streaming responses—used for chat and text generation—now include real-time cost counters in the response metadata. Each chunk of tokens is accompanied by a cumulative cost field, allowing clients to abort a generation if the cost exceeds a threshold. This has led to a new class of "cost-aware" clients that monitor spend token by token and adjust generation parameters on the fly, such as reducing the maximum output length or switching to a cheaper model mid-stream.
Batch APIs introduced per-request price caps. Previously, batch pricing was based on total token count, with no per-request limit. Now, each request in a batch is billed individually, with a cap that prevents a single long request from dominating the cost. This change required providers to implement request-level accounting in their batch schedulers, adding overhead but enabling more predictable billing for customers.
Authentication tokens now embed rate-limit tiers that correspond to per-token price brackets. A "basic" tier might have a higher per-token price but no volume commitment, while a "premium" tier offers a lower per-token price in exchange for a monthly minimum. This tiered pricing model, common in SaaS, is new to inference APIs and has deepened vendor lock-in: migrating to another provider requires renegotiating the tier and potentially losing the volume discount.
Custom billing schemas have become a differentiator. One provider introduced a "training inference" schema that charges per-token at a flat rate regardless of model size, simplifying cost forecasting for training teams. Another provider offers a "spot inference" schema with dynamically adjusted per-token prices based on real-time GPU availability. These schemas are not standardized, making it harder for customers to compare costs across providers.
The API changes also introduced new failure modes. For example, a client that set an overly aggressive X-Token-Budget might receive frequent 429 responses, leading to retries and increased latency. One team reported that their cost-aware client entered a retry loop, generating more tokens in retries than the original request would have consumed. This led to the development of "budget-aware" retry logic that backs off when the budget is too tight.
The Financial Ripple Effect on Model Training
The most direct effect was on training data budgets. One lab, facing a 30% overrun in its inference costs, cut its training data size by roughly 30%—from 2 trillion tokens to 1.4 trillion—to stay within its overall budget. The reduction was not random; the team used a cost-per-token analysis to identify high-cost data sources (e.g., long documents with low information density) and removed them first. The resulting model performed slightly worse on long-context tasks but met the budget.
Another lab switched to a smaller base model mid-cycle. The original plan was to train a 70B-parameter model from scratch, but after the per-token price drop, the cost of evaluating that model during training became prohibitive. The team pivoted to a 30B-parameter architecture, reducing inference cost by roughly 60% at the expense of some accuracy. The decision was made in a single meeting after reviewing the per-token cost projections.
Industry analysts now estimate that inference cost accounts for 15–25% of total training spend for large language models, up from roughly 5–10% a year ago. This shift is driven partly by the increased use of test-time compute (e.g., chain-of-thought and self-consistency) and partly by the per-token pricing model itself, which makes inference costs more visible and thus more likely to be budgeted.
Venture funding terms have begun to reflect this reality. Several recent Series A and B rounds for AI startups include clauses that tie funding tranches to inference cost targets. One term sheet, reviewed by this reporter, required the startup to keep per-token inference cost below $0.00003 for its flagship model, with a penalty in the form of reduced valuation if the target is missed. Startups are now negotiating per-token caps in cloud contracts, treating them as a key business metric alongside latency and throughput.
Not everyone agrees that per-token pricing is a net positive. Some argue that it adds unnecessary complexity and favors large labs that can negotiate volume discounts. Smaller teams, they claim, are better off with a simpler GPU-hour model that aligns with hardware costs. This tension between simplicity and granularity is likely to persist as the market matures. In the meantime, the ripple effects of that single contract continue to reshape how training pipelines are built, budgeted, and optimized.
Lessons for Engineering Teams
The first lesson is to build cost-monitoring into training pipelines early. Teams that waited until after the contract was signed to add cost tracking found themselves scrambling to understand their cost structure. A simple dashboard that logs per-token cost per evaluation run, with alerts for spikes, can pay for itself in avoided overruns.
The second lesson is to negotiate inference price ceilings, not just compute time. Many cloud contracts still focus on GPU-hours or compute units, ignoring per-token pricing. Teams should ask for a maximum per-token price for inference, with automatic discounts if actual usage exceeds a threshold. This provides predictability even as model architectures change.
The third lesson is to benchmark per-token cost across providers quarterly. The market is moving fast; a provider that was cheapest six months ago may no longer be. One team that benchmarked regularly found that Provider B's per-token price had dropped 20% relative to Provider A over a quarter, prompting a migration that saved 15% on inference costs.
The fourth lesson is to design model architectures with inference cost in mind. Techniques like speculative decoding, multi-query attention, and KV-cache quantization can reduce per-token cost by 30–50% without significant accuracy loss. Teams that ignored these techniques during training found themselves locked into expensive inference pipelines.
Finally, prepare for contract-driven pipeline rewrites. The per-token price drop was a one-time event, but similar shocks are likely as the market matures. Engineering teams should design training pipelines with modular cost components—e.g., a separate evaluation service that can be swapped out—so that a change in pricing does not require a full pipeline rewrite. The teams that did this were able to adapt within weeks; those that did not took months.